- No GPU on your line
- Inference runs on CPU — PyTorch is installed in its CPU-only build, deliberately. An ordinary server is enough, which changes both what the installation costs and how long it takes to get one.
- Your setup is a plugin, never a fork
- One customer means one isolated stack, and anything specific to you lives in its own plugin. Nobody copies the product to bend it — a copy drifts, stops receiving fixes, and becomes yours to maintain.
- Going back is changing a tag
- Every service ships as a container and every image carries its version tag. A model version that behaves worse on your parts is rolled back the same way as any other release.
- History is a database, and it is backed up
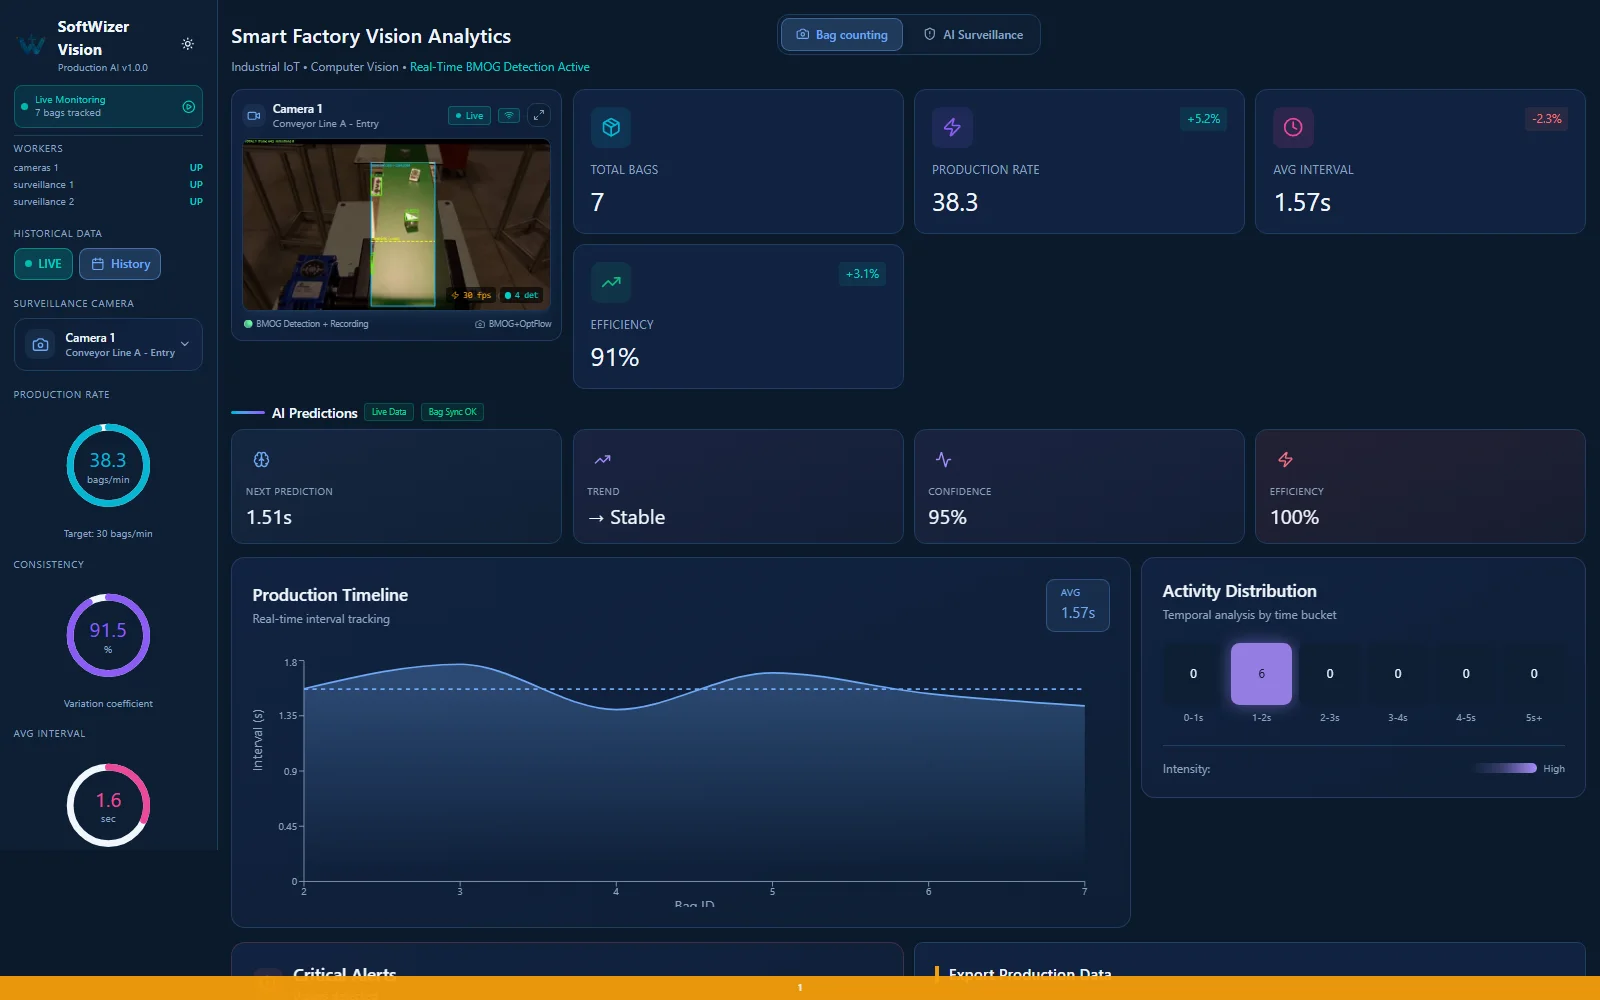
- Counts and stoppages land in a time-series database, with monitoring and an automated backup service shipped alongside — not a folder someone remembers to copy.